Web Scraping with htmlparse
JM 4 Dec 2012 - Here is a minimal example of Web scraping using htmlparse
An excerpt, from htmlparse documentation, states the following:
- Each node in the generated tree represent one tag in the input.
- The name of the tag is stored in the attribute type of the node.
- Any html attributes coming with the tag are stored unmodified in the attribute data of the tag.
- In other words, the command does not parse html attributes into their names and values.
If a tag contains text its node will have children of type PCDATA containing this text. The text will be stored in the attribute data of these children.
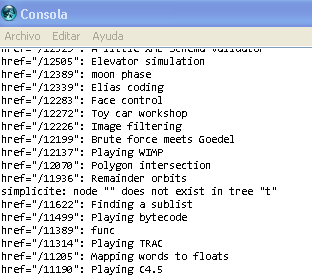
As I am a RS fan, I am getting a list of all his recent projects.
- This is an unfinished code just to show the overall mechanism.
- notice that I am getting just one link per bullet, so, for example, I am missing the link for A pocket Wiki, which is the second link on the 5th bullet. see how ONLY Profiling with execution traces is being listed.
- also, notice the error message "node "" does not exist in tree "t"" when there is no link on the bullet, as in "simplicite"
getting as many links per bullet could be a good exercise for the reader.
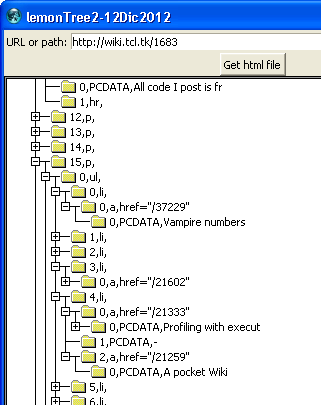
As a side note, I used LemonTree branch to easily find the location of the bulleted list block that I am parsing.
Ways of accessing the data
Walking the tree
JM 1/4/2019 Adjusted for nikit
package require struct
package require htmlparse
package require http
package require tls
console show

namespace eval ::scraper {
    # The tag at $startNodePath should be a <ul> with its children having the
    # structure of <li><a href="...">...</a><li>.
    proc parse-list-of-links {url startNodePath} {
        set documentTree [::struct::tree]
        http::register https 443 tls::socket
        set conn [::http::geturl $url]
        set html [::http::data $conn]
        ::http::cleanup $conn

        htmlparse::2tree $html $documentTree
        htmlparse::removeVisualFluff $documentTree
        htmlparse::removeFormDefs $documentTree

        set base [walk $documentTree $startNodePath]
        puts "data: [$documentTree get $base data]"
        puts "type(tag): [$documentTree get $base type]\n"
        update
        #return

        # Start with the first child of the base tag.
        set li [walkf $documentTree $base {0}]
        while {$li ne ""} {
            #set link [$documentTree get [walkf $documentTree $li {0 0}] data]
            set link "error"
            catch {$documentTree get [walkf $documentTree $li {0}] data} link
            regexp {href='(.*)'} $link => link
            catch {$documentTree get [walkf $documentTree $li {0 0}] data} title
            puts "https://wiki.tcl-lang.org${link}: $title"
            # Go from the current li to its sibling node.
            set li [$documentTree next $li]
        }

        $documentTree destroy
        return
    }

    proc walkf {tree startNode path} {
        set node $startNode
        foreach idx $path {
            if {$node eq ""} {
                break
            }
            set node [lindex [$tree children $node] $idx]
        }
        return $node
    }

    proc walk {tree path} {
        return [walkf $tree root $path]
    }
}

::scraper::parse-list-of-links "https://wiki.tcl-lang.org/page/RS" {1 9 3}
dbohdan 2015-01-11: I found the example code above hard to understand, so I updated it with some comments as well as variable and proc names that I think clarify what the script does at each step. JM, I hope you don't mind my changes.
JM 2015-01-14: Of course not, this is much better, thanks!
TreeQL
dbohdan 2015-01-11: The following script scrapes the same data as the one above but processes multiple links in each list item, not just the first one. This is done using TreeQL queries with which manipulating every child node of a given node comes naturally.
This neat little language appears to be severely underused by tclers. Consider that it provide access to hierarchical documents in the age of the Web and is already there in Tcllib. The lack of examples on the wiki may be one reason for it, so I've added the one I wrote while figuring it out at Web Scraping with htmlparse
Processing trees generated by htmlparse seems like the killer app for TreeQL. The man page could use more examples as well.
JM 7/23/2019 - updated for nikit
package require struct
package require fileutil
package require htmlparse
package require http
package require treeql 1.3
package require tls

console show

proc parse-treeql {url} {
    set documentTree [::struct::tree]

    http::register https 443 tls::socket
    set conn [::http::geturl $url]
    set html [::http::data $conn]
    ::http::cleanup $conn

    htmlparse::2tree $html $documentTree

    treeql q1 -tree $documentTree
    treeql q2 -tree $documentTree

    q1 query tree withatt type ul
    set ul [lindex [q1 result] 9]
    q1 query replace $ul children children map x {
        # For each li in the ul...
        q2 query replace $x get data
        set link [lindex [q2 result] 0]
        q2 query replace $x children get data
        set title [lindex [q2 result] 0]
        if {$title ne ""} {
            puts "$link: $title"
        }
    }

    q1 discard
    q2 discard
    $documentTree destroy

    return
}

parse-treeql "https://wiki.tcl-lang.org/page/RS"
Selectors
With treeselect you can use CSS selector-like queries to access the elements of an HTML document stored in a tree object.
To run this example you will need a copy of the treeselect module in the same directory. You can download it with wiki-reaper: wiki-reaper 41023 0 10 > treeselect-0.3.2.tm.
::tcl::tm::path add .
package require treeselect 0.3

set tree [::treeselect::url-to-tree "https://wiki.tcl-lang.org/1683"]
set anchorNodes [::treeselect::query $tree {
    hmstart html body .container #wrapper div#content
    p:nth-child(10) ul li a
}]
foreach node $anchorNodes {
    set link [$tree get $node data]
    set title [$tree get \
            [::treeselect::query $tree "PCDATA" $node] data]
    puts "$link: $title"
}
Related links:
https://core.tcl-lang.org/tcllib/doc/trunk/embedded/md/tcllib/files/modules/struct/struct_tree.md
https://core.tcl-lang.org/tcllib/doc/trunk/embedded/md/tcllib/files/modules/htmlparse/htmlparse.md
https://core.tcl-lang.org/tcllib/doc/trunk/embedded/md/tcllib/files/modules/treeql/treeql.md